Happy Hour and Dinner at Educause 2026
September 29
How can researchers use LLM agents for real work while keeping the methods and evidence needed to check their results? This two-hour session builds on two years of SC and PEARC workshops to present emerging practices for agentic engineering in research.
We will examine agents as librarians that organize project knowledge and orchestrators that coordinate tasks and call deterministic tools. Git and Data Version Control preserve the project record beyond any one conversation or model. That record makes the work traceable; testing and scientific judgment are still needed to assess its conclusions. A prepared example will follow source data through analysis to a report linked to its evidence. We will use it to show a failed check, recovery, and continuation with a different model.
Participants will learn to build small benchmarks from their own work and define what counts as a successful result. We will compare models on tasks set aside for evaluation and repeat tests to assess consistency. Those results will guide choices between local and commercial models. We will test whether routing tasks between models improves on using one model throughout. The comparison will account for answer quality, cost, and the time people spend reviewing and correcting results.
We will discuss deployment options for the tools and infrastructure, including desktop systems such as the AMD Ryzen AI Halo and the NVIDIA DGX Spark, as well as personal and shared hosted services. No particular hardware or prior workshop attendance is required. Participants will leave with practical methods for choosing models and preserving the evidence others need to evaluate, continue, or reproduce the work.
After the event, head up to the rooftop for complimentary lunch, drinks, and breathtaking views! Event Details: Bites, Brews & Bird's-Eye Views @ VU Rooftop
Check out other great events during conference week!
PetaFLOP 2026 @ the Field Museum
Just a hop across the 3rd Floor Skybridge to HGI McCormick and you're right at the Commodore | Hudson meeting rooms! Super close and easy to find - just follow the signs!
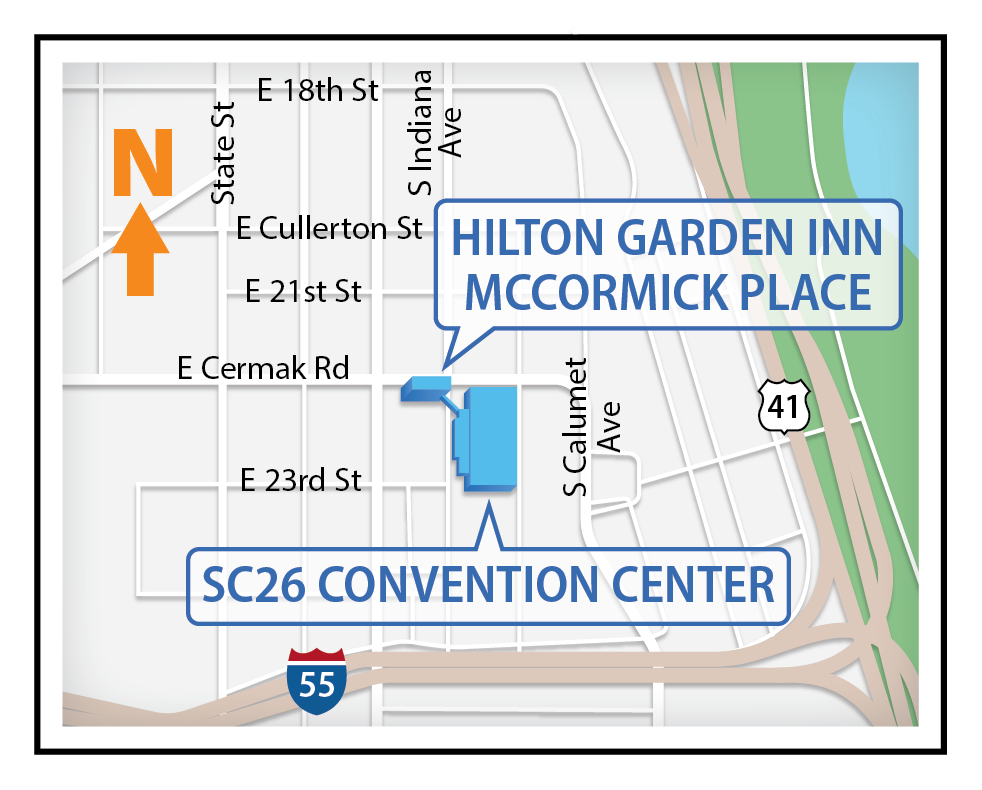
Location
Date & Time
Mon., November 16, 2026,
10:30 AM - 12:30 PM CT
10:30 AM - 12:30 PM CT
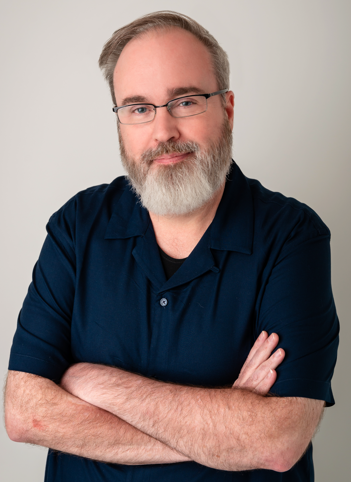
About the Speaker
Dr. Christopher S. Simmons is Scientist-in-Residence at Cambridge Computer, where he works with research institutions on high-performance computing, AI and research data infrastructure. He earned his Ph.D. in Physical Chemistry at the University of Texas at Austin and served as research faculty and Deputy Director of the Center for Predictive Engineering and Computational Science (PECOS) at UT Austin’s Oden Institute. He later led research computing at UT Dallas before joining MIT as Deputy Executive Director of the Massachusetts Green High Performance Computing Center (MGHPCC). A founder and former project lead of OpenHPC, he remains active in its leadership as outreach and engagement coordinator and volunteers with the Open Storage Network. He brings more than 25 years of experience in large-scale simulation on NSF, NASA and DOE leadership-class systems.
Join us on Monday, November 16!